Embedded AI
We take a model that works on your laptop and make it run on your microcontroller or edge board, inside the RAM, flash, latency and power budget the hardware actually has.
Start a Project- Model Quantization
- LiteRT .tflite / Executorch .pte
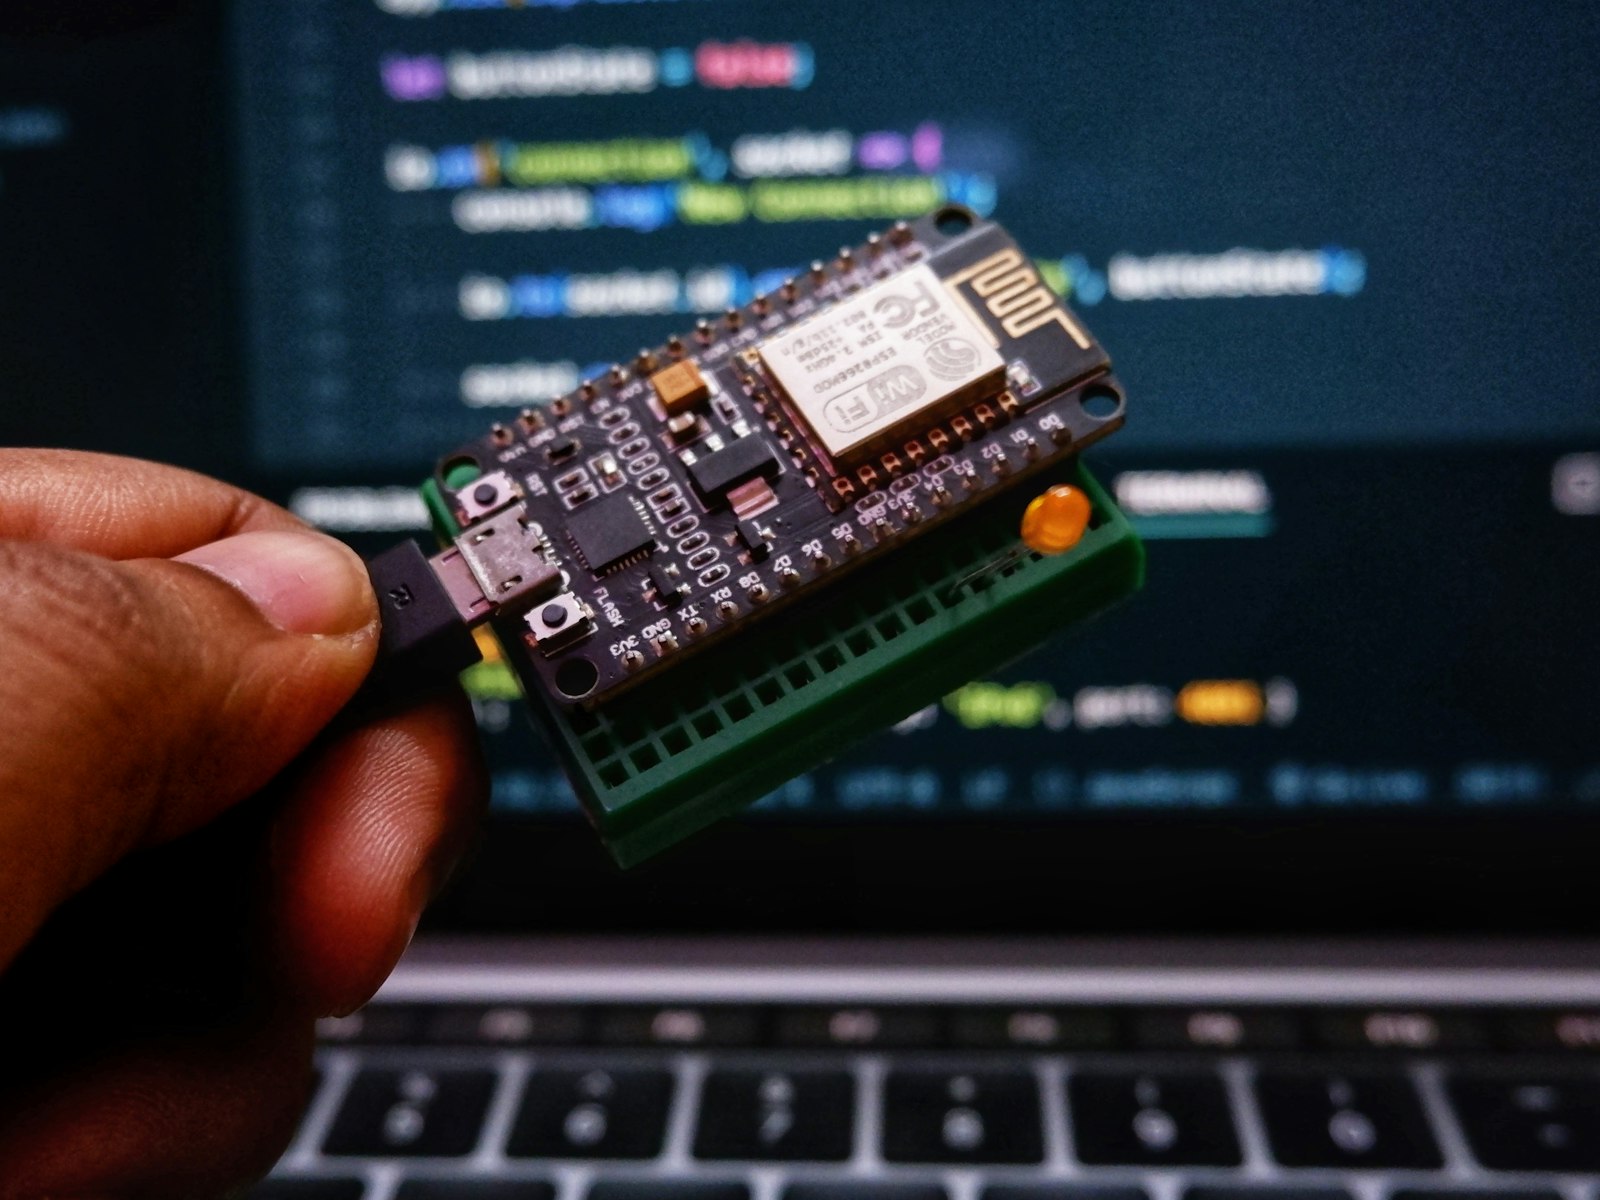
When do you need embedded AI engineering?
When the model is accurate but the device can't run it: it doesn't fit in flash, it misses the frame deadline, or the battery is gone by lunch. Training is rarely the problem at that point. Getting the model onto the chip is.
What do we actually do?
We start from your trained model (or the dataset and the task) and the numbers the device has to hit. From there:
- Quantize to INT8 or FP16 and measure the accuracy you lose against your float baseline
- Prune where the accuracy budget allows it
- Export to LiteRT (
.tflite) or ExecuTorch (.pte) for the runtime on your target - Benchmark on the real board, not an emulator
What do you get at the end?
A converted model, the benchmark numbers from your hardware, and a written note on every accuracy trade-off we made, so your team can repeat the process when the model changes.
Why work with us on this?
We test on off-the-shelf boards (Raspberry Pi, Jetson, ESP32, STM32) before anyone commits to custom hardware. On CORTEX-Health, quantization cut inference time by 40% on the diagnosis pipeline.
Other services
Robotics & Control
Deterministic Motion Planning. Real-time state estimation, 6-DOF trajectory generation, and closed-loop contr…
Computer Vision
Edge-Native Vision Intelligence. Low-latency object detection, semantic segmentation, and vision pipelines.
Industrial IoT
Cloud-native machines. Robust telemetry pipelines that handle millions of data points.
Backend & API
High-performance servers to manage your device fleet. Built with Django / FastAPI.
Ready to build something real?
Tell us the hardware, the constraint and the deadline. You'll talk to the engineer who'd do the work.
Start a Project